Infrastructure atlas AWS/Inference accelerator
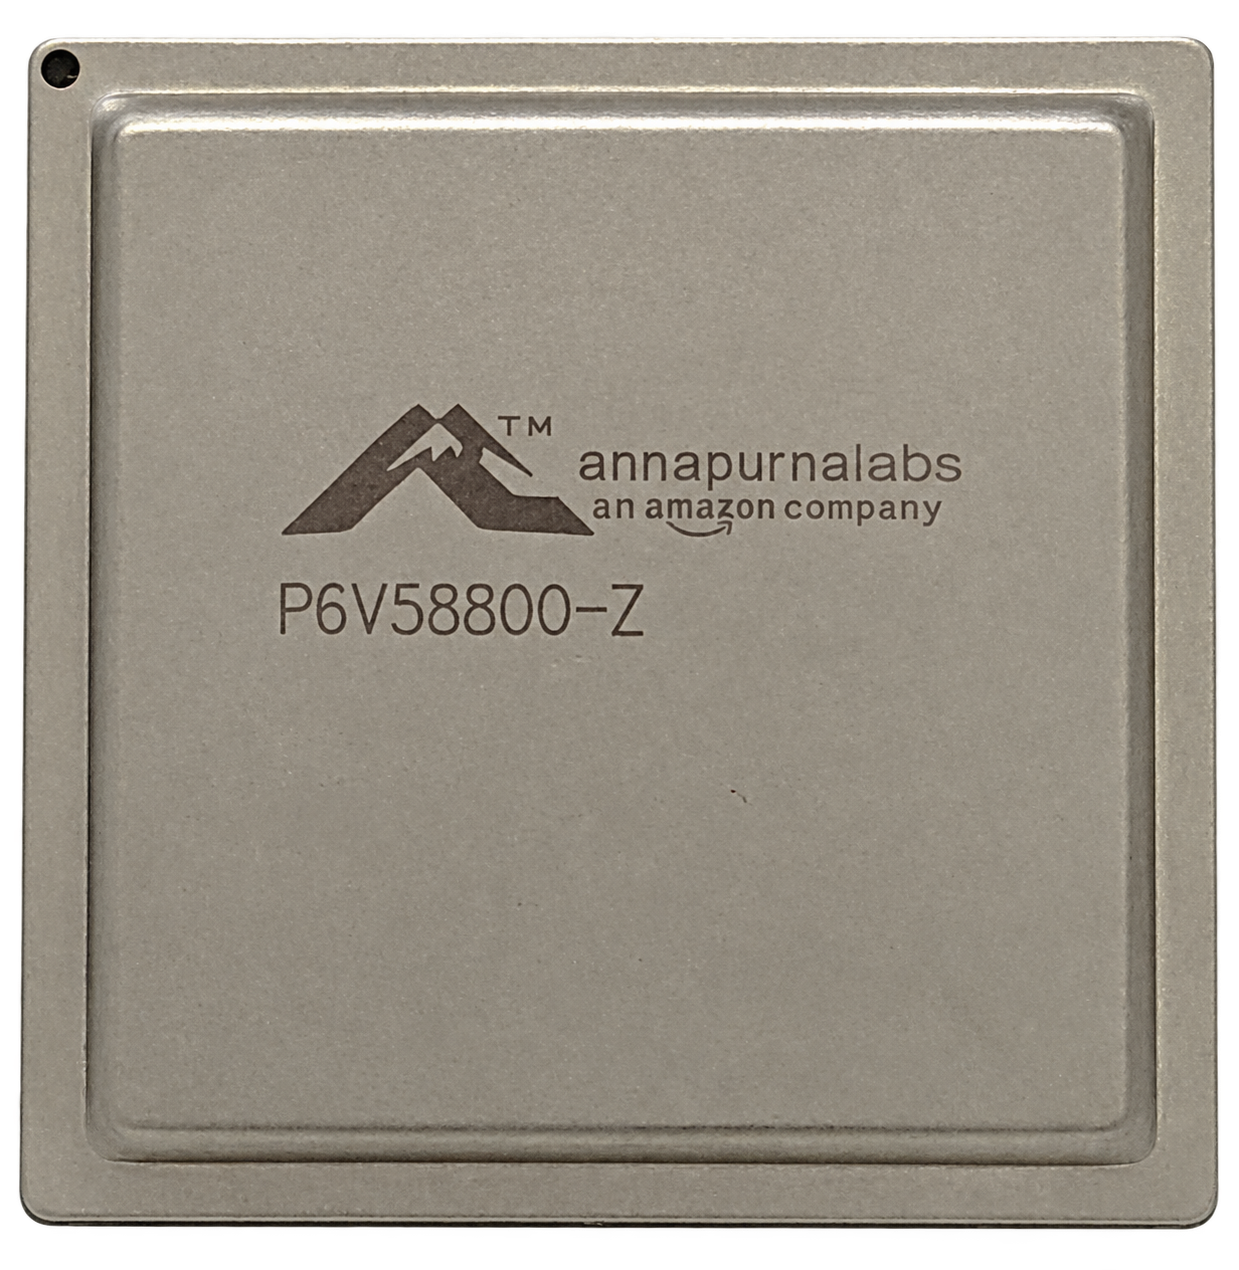 Inferentia family package photo · not v2-specific
AWS/Inference acceleratorInferentia2
AWS’s inference-first accelerator for cost-efficient production serving through Inf2 instances and the Neuron SDK.
ASICInferentiainferenceAWS NeuronASIC
Inferentia family package photo · not v2-specificPrecision & peak compute
| Precision | Published peak | Basis |
|---|---|---|
| FP16 | 190 TFLOPS | Per chip · AWS published peak |
Peak FLOPS and TOPS are theoretical hardware figures. Sparse and dense modes, chip and system totals, and form factors are not interchangeable.
AWS Inferentia2 documentation