The physical layer
Infrastructure atlas.
A source-linked field guide to the chips, systems, and platforms behind model performance.
Accelerators
17 of 17 records
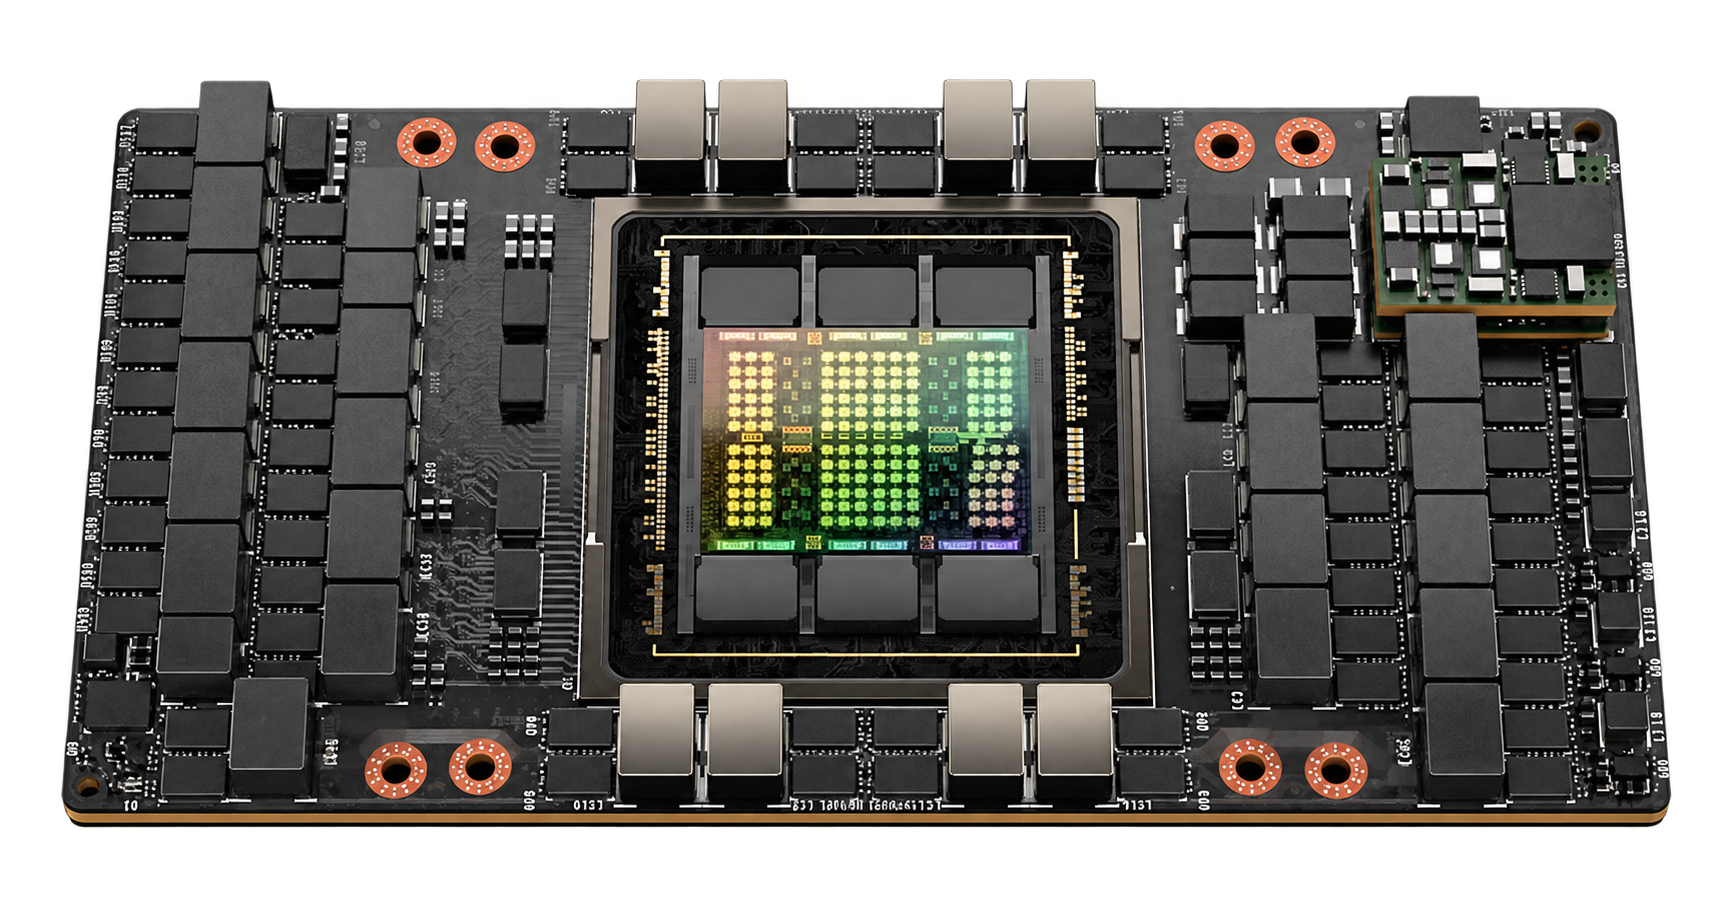 Physical hardware

H100 Tensor Core
A Hopper data-center GPU with Tensor Cores, Transformer Engine FP8, NVLink, and MIG partitioning.
Memory
80 GB HBM3
Bandwidth
3.35 TB/s
Power
Up to 700 W
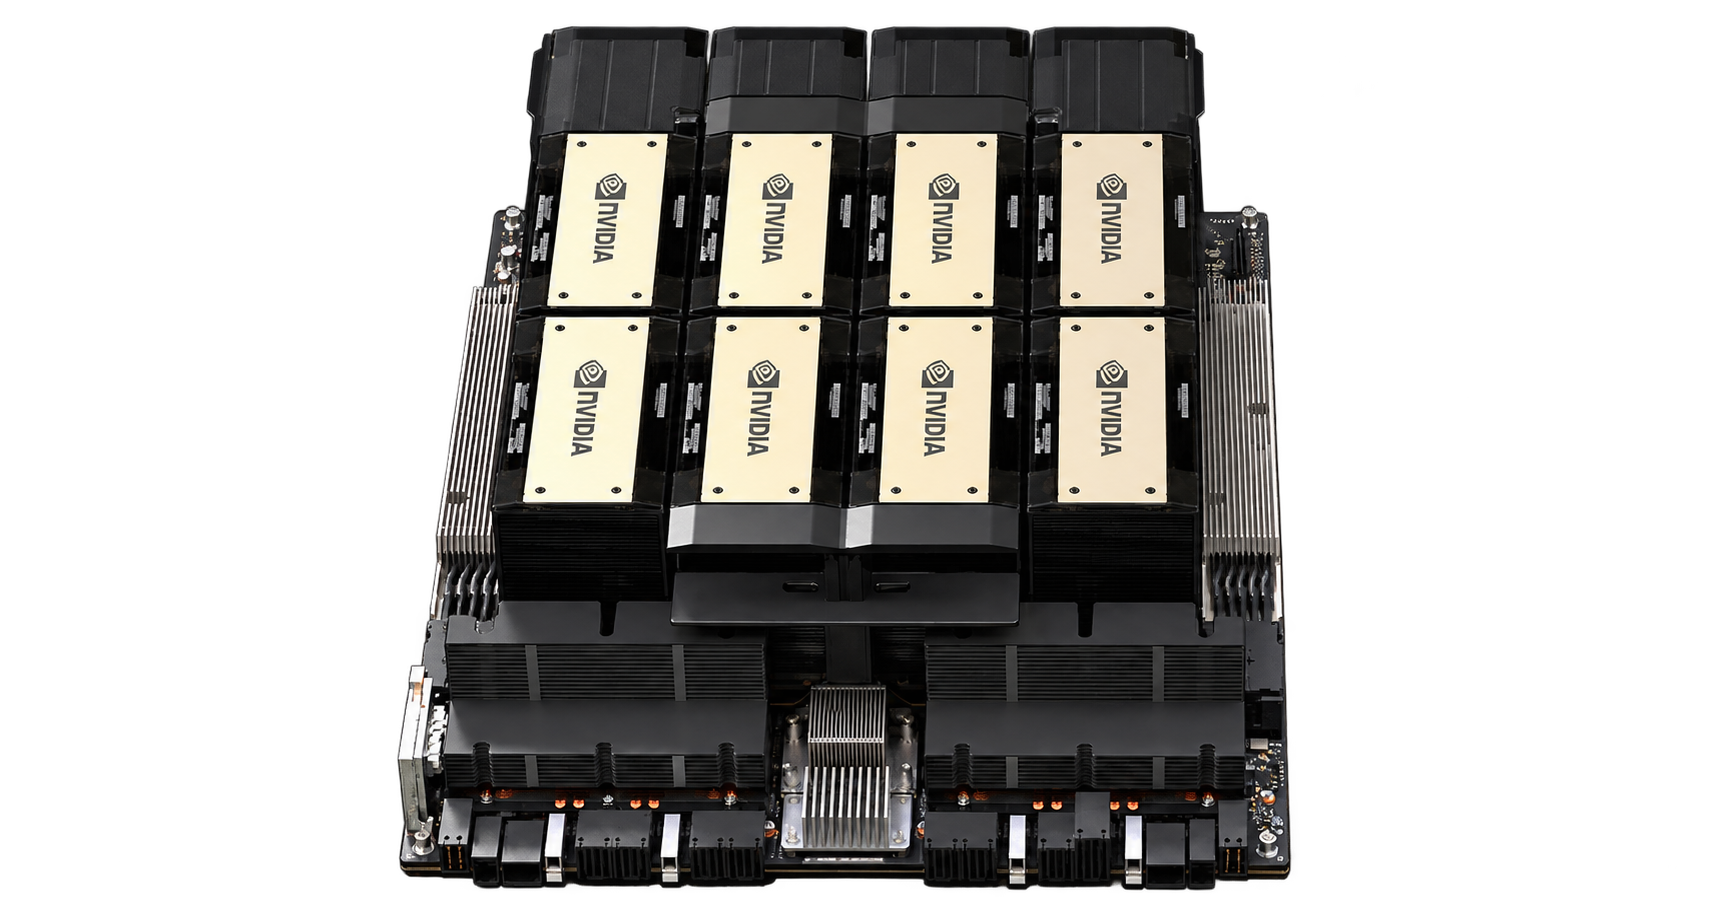 Physical hardware
H200 Tensor Core
Hopper’s memory-heavy sibling, built around 141 GB of HBM3e for larger models and KV caches.
Memory
141 GB HBM3e
Bandwidth
4.8 TB/s
Power
Up to 700 W
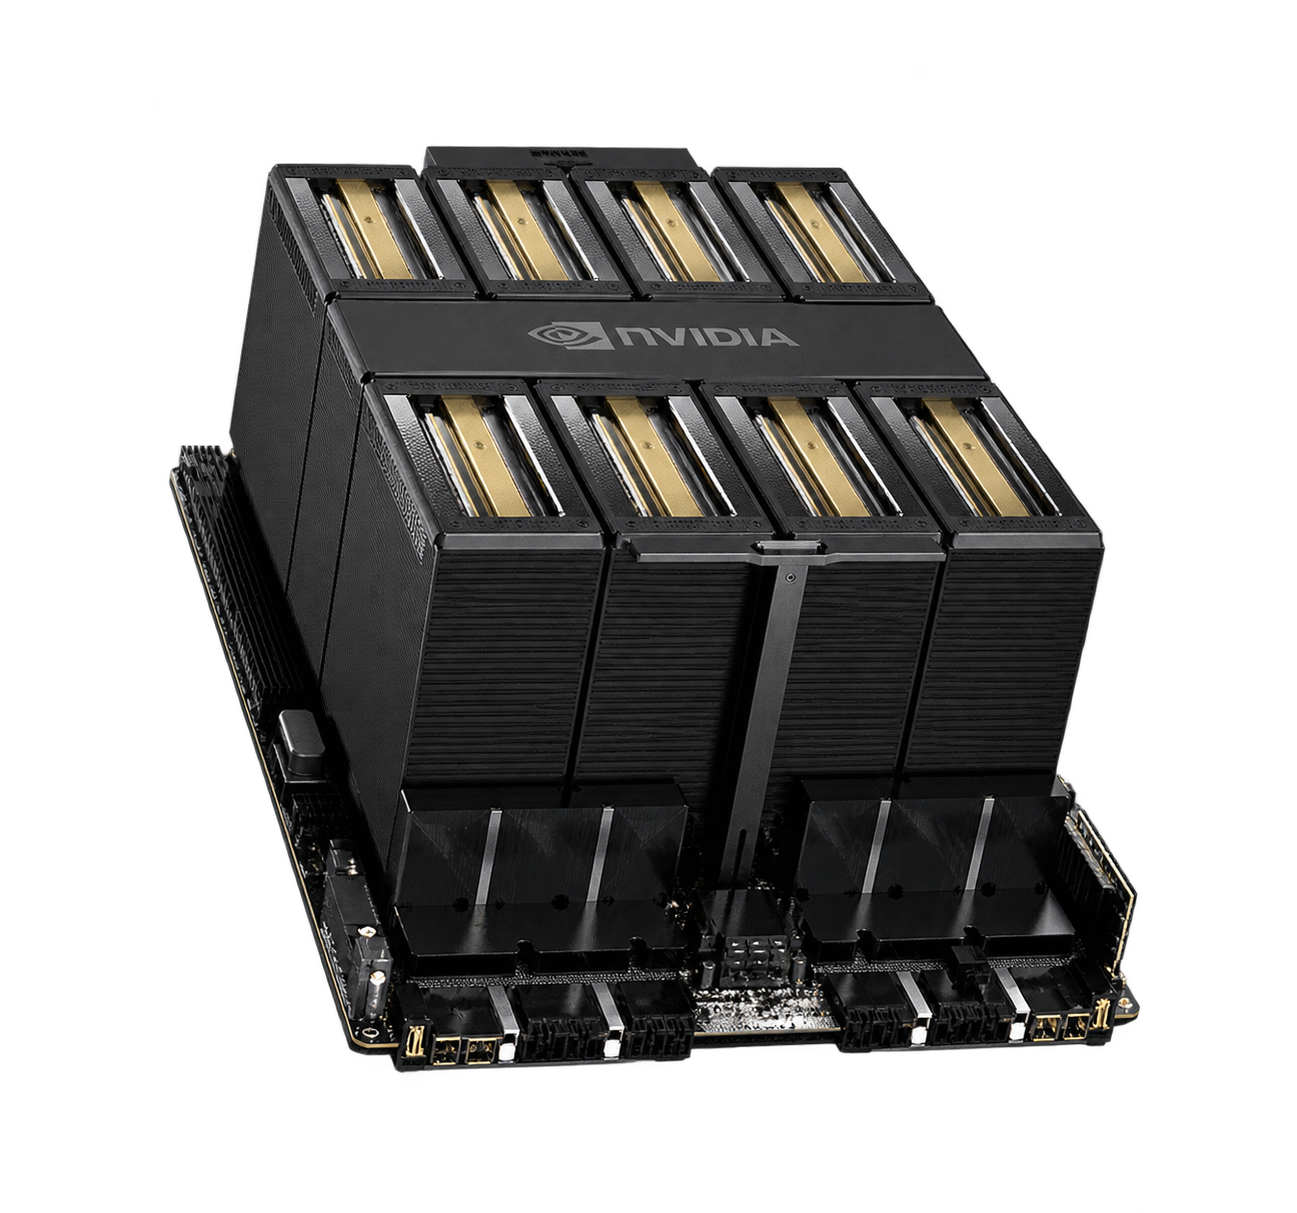 Physical hardware
B200 Tensor Core
Blackwell’s data-center GPU for FP4/FP6/FP8 workloads, with a large HBM3e memory pool and fifth-generation NVLink.
Memory
180 GB HBM3e
Bandwidth
Up to 8 TB/s
Compute
FP4 / FP6 / FP8
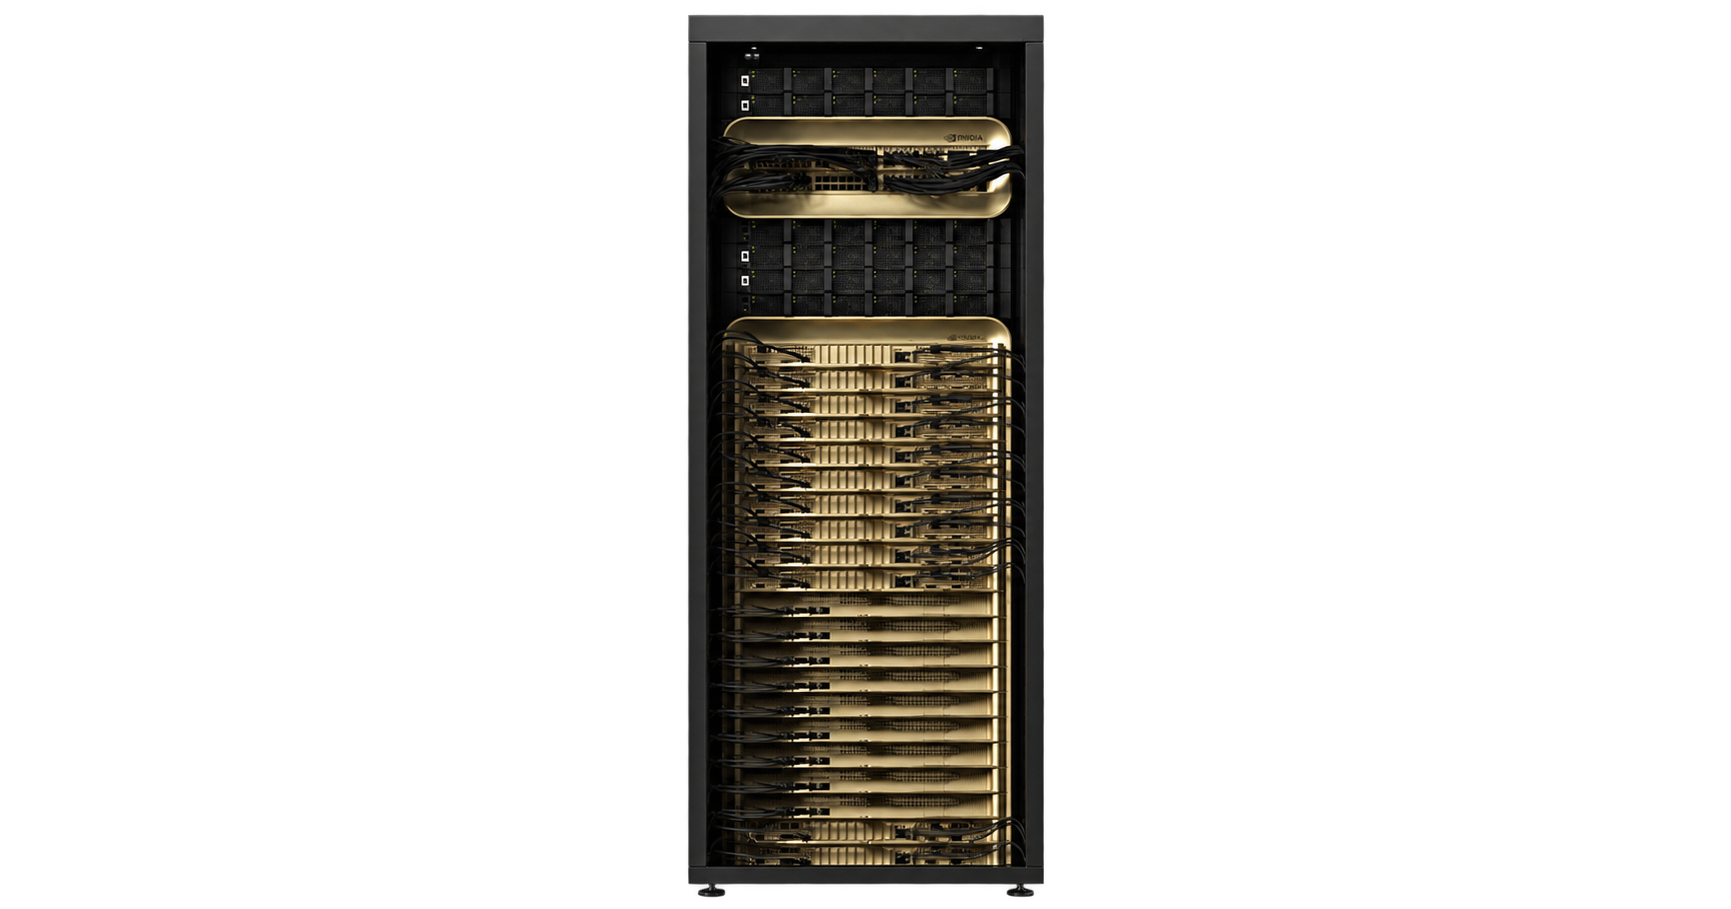 Physical hardware
GB200 NVL72
A liquid-cooled rack-scale domain that treats 72 Blackwell GPUs and 36 Grace CPUs as one tightly coupled AI system.
GPU count
72 B200
Unified memory
30 TB
GPU fabric
130 TB/s
 Physical hardware
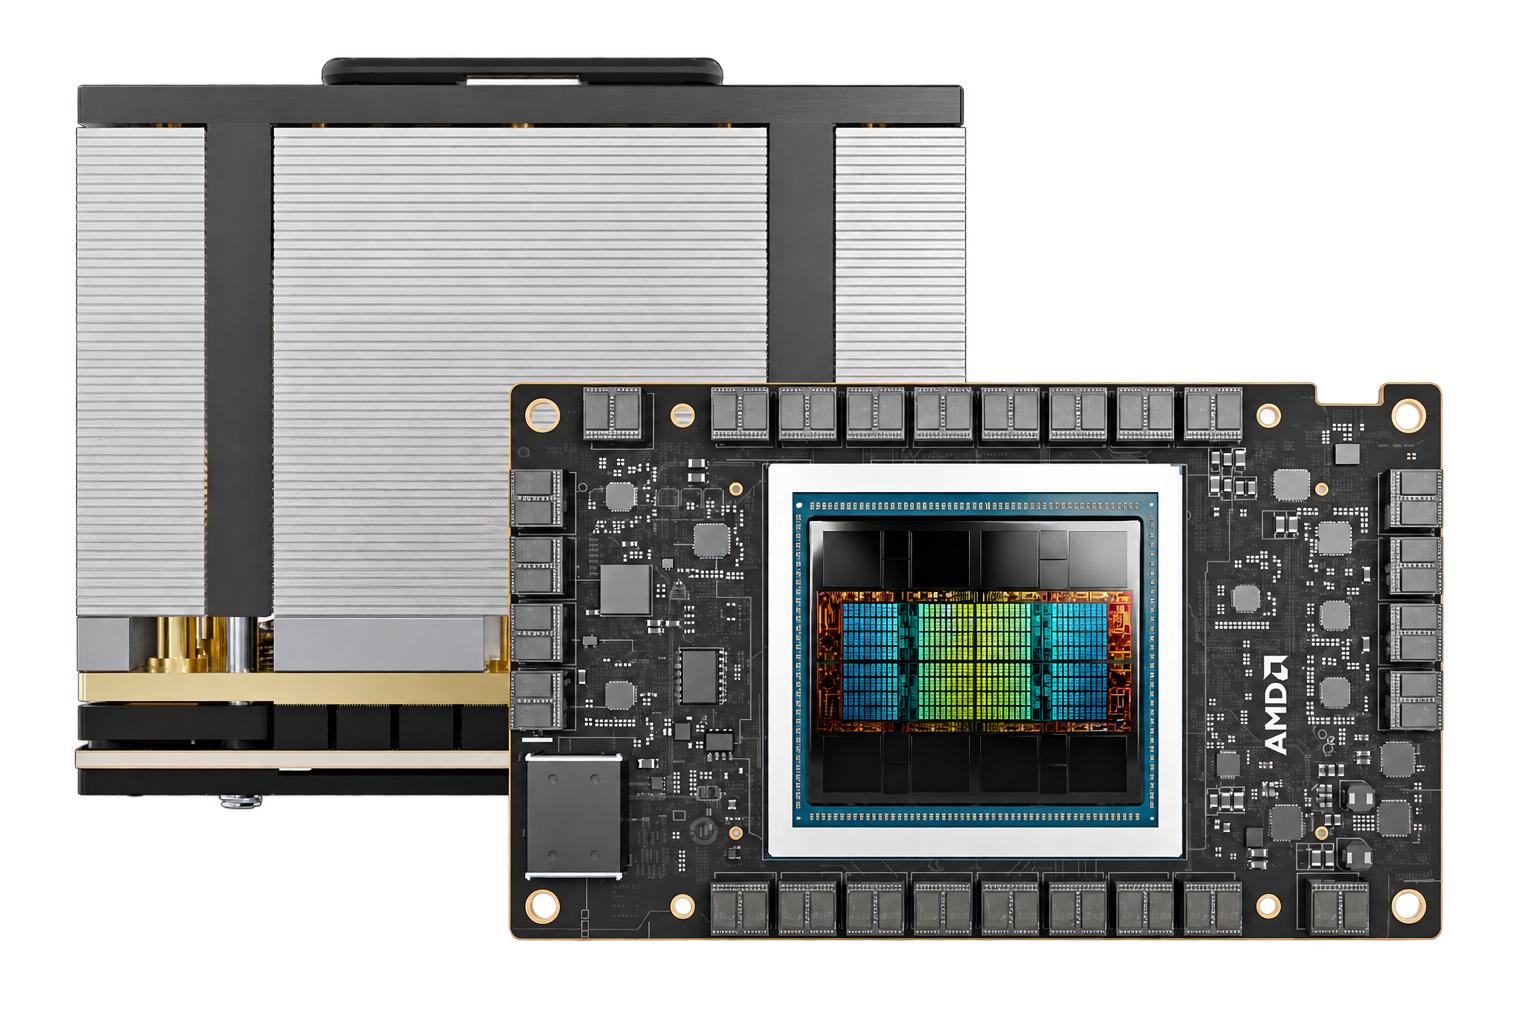
Instinct MI300X
A memory-dense OAM accelerator with 192 GB HBM3 and ROCm as its primary software ecosystem.
Memory
192 GB HBM3
Bandwidth
5.3 TB/s
Power
750 W
 Physical hardware
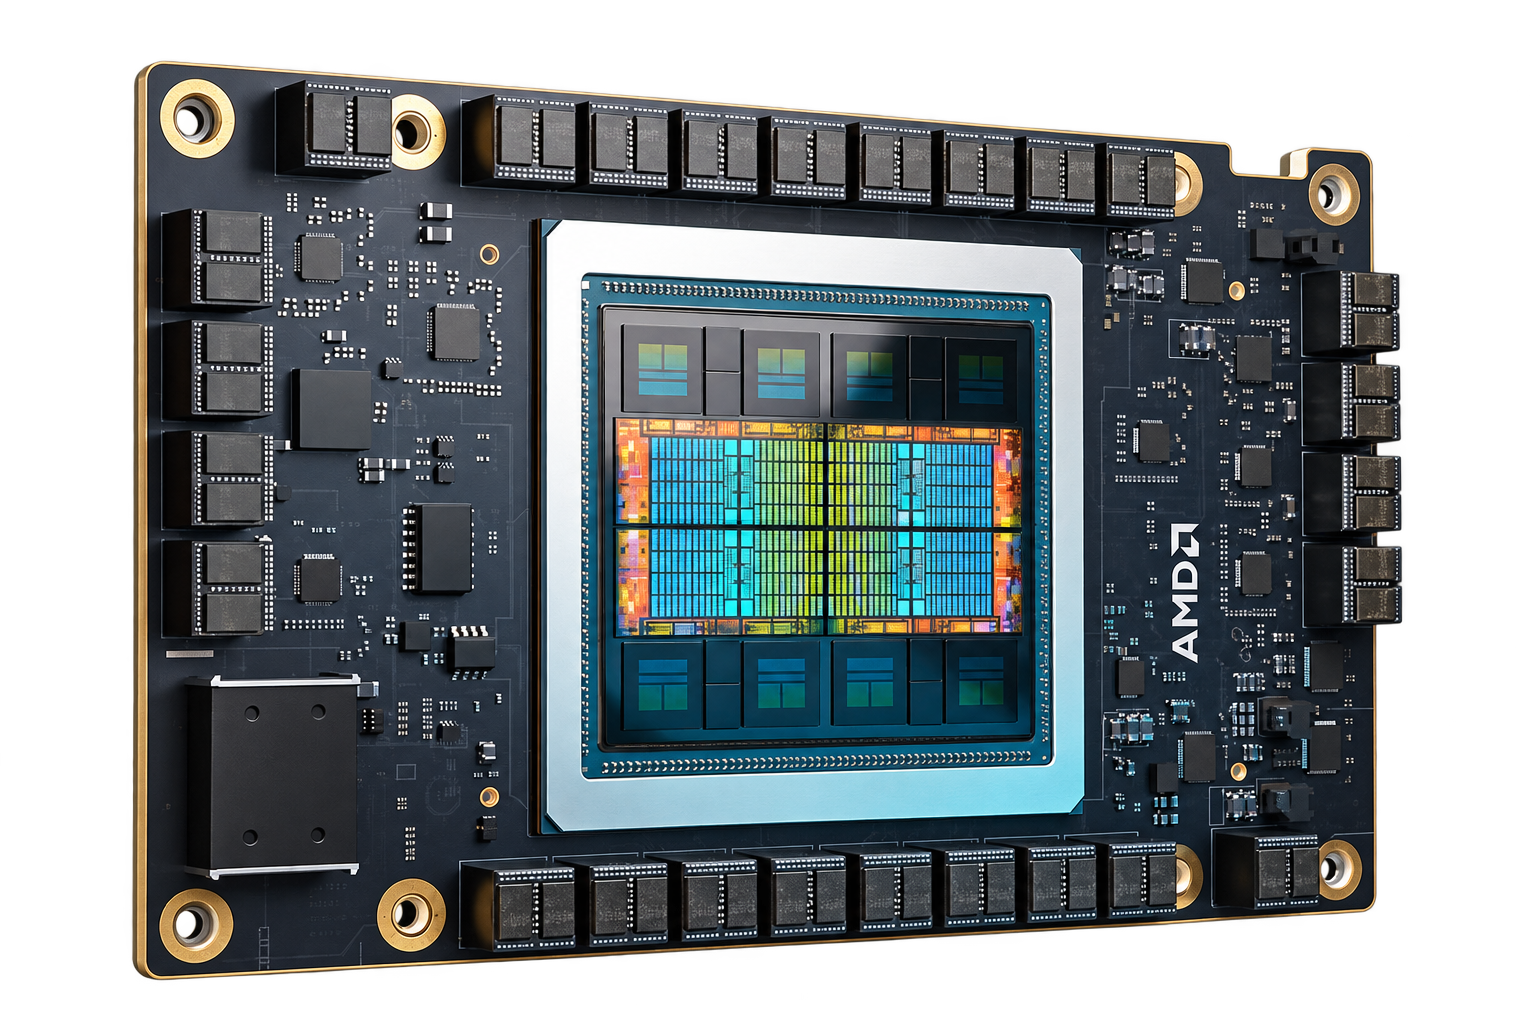
Instinct MI325X
A CDNA 3 refresh that increases the memory pool to 256 GB HBM3e for high-parameter inference and training.
Memory
256 GB HBM3e
Bandwidth
6 TB/s
Platform
2 TB HBM3e
 Physical hardware
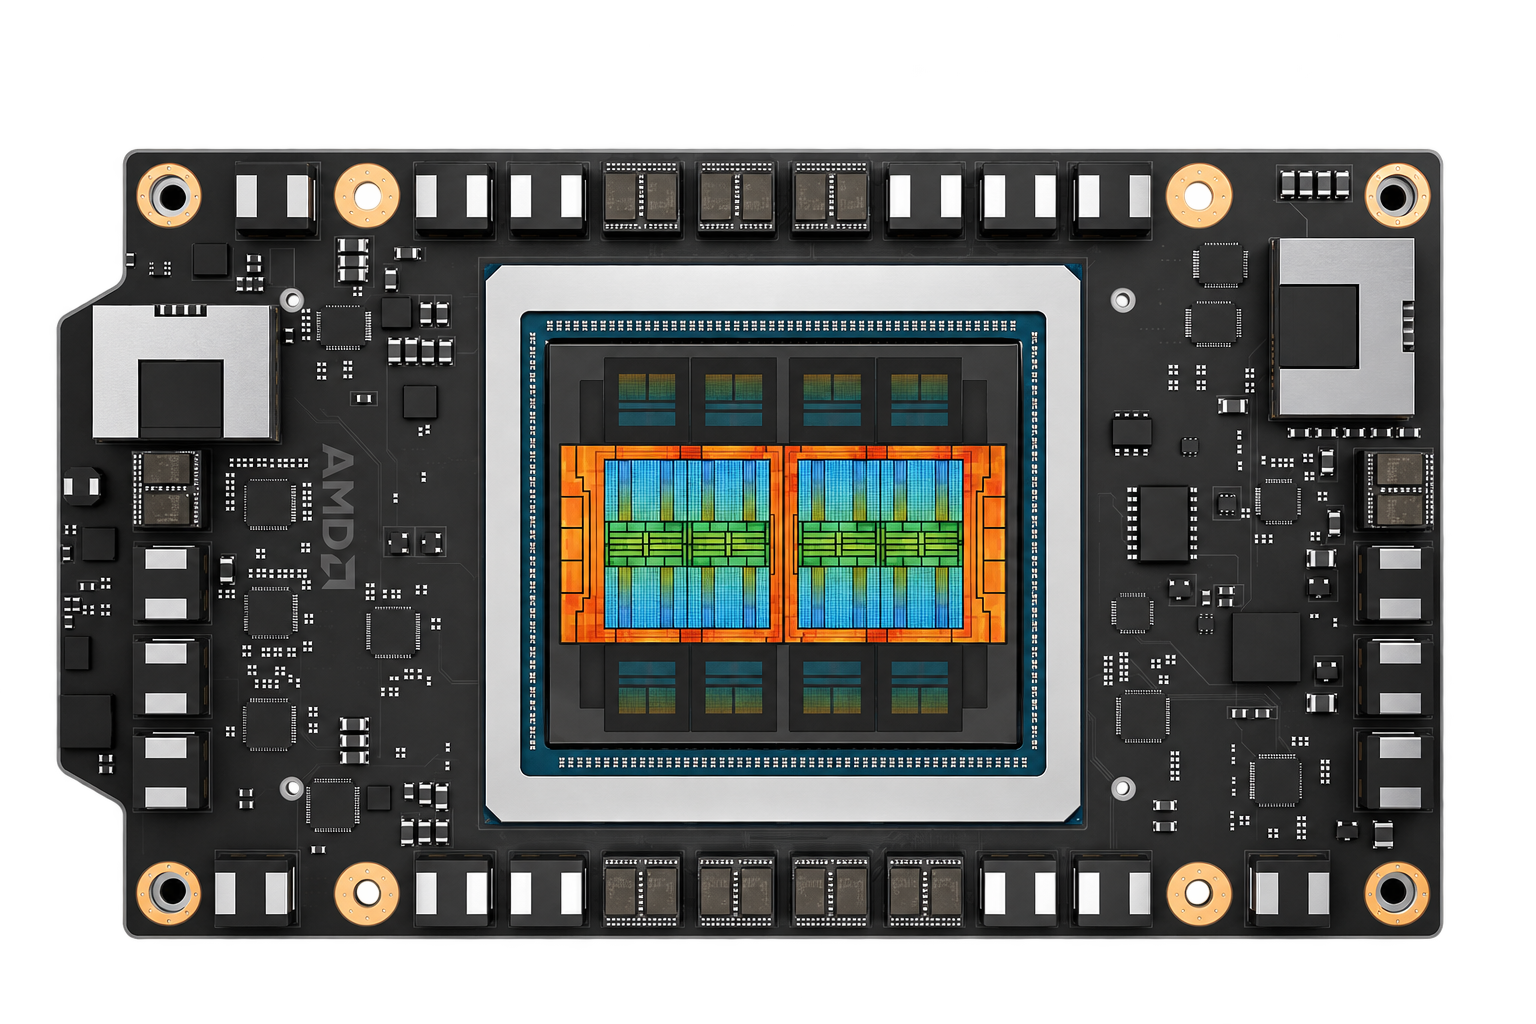
Instinct MI355X
A fourth-generation CDNA accelerator with 288 GB HBM3e, 8 TB/s bandwidth, and native microscaling formats.
Memory
288 GB HBM3e
Bandwidth
8 TB/s
Power
1,400 W
 Physical hardware

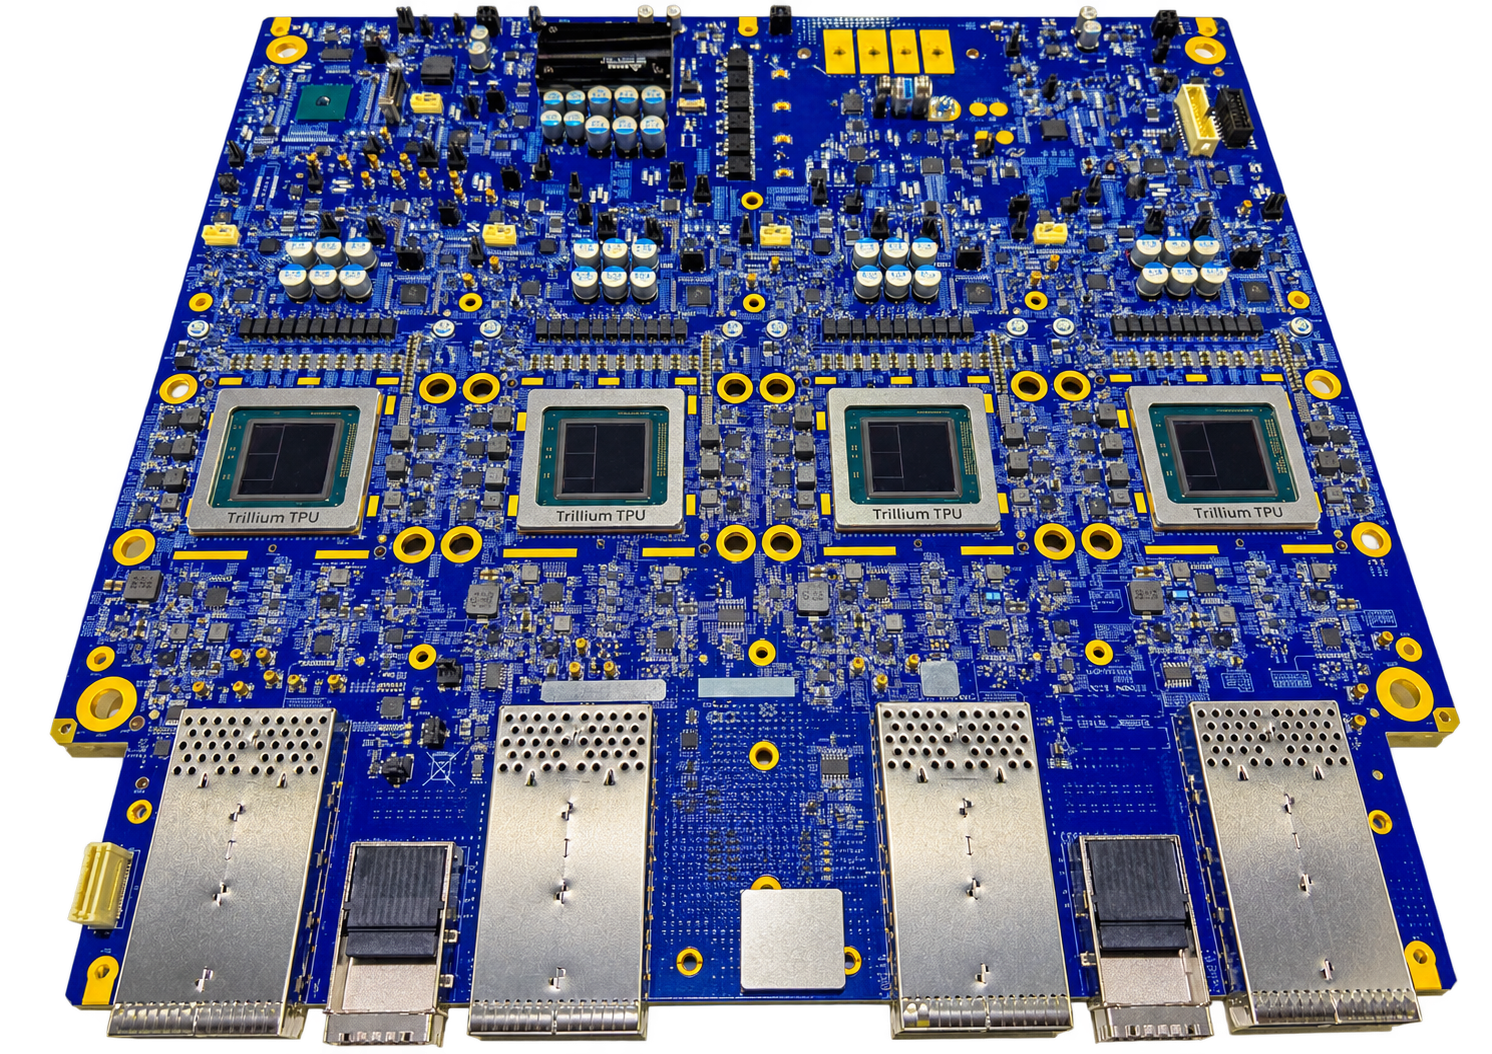
Cloud TPU v6e / Trillium
Google’s sixth-generation TPU for transformer, text-to-image, and CNN training, fine-tuning, and serving.
Memory
32 GB HBM
Bandwidth
1,638 GB/s
Pod
256 chips
 Physical hardware

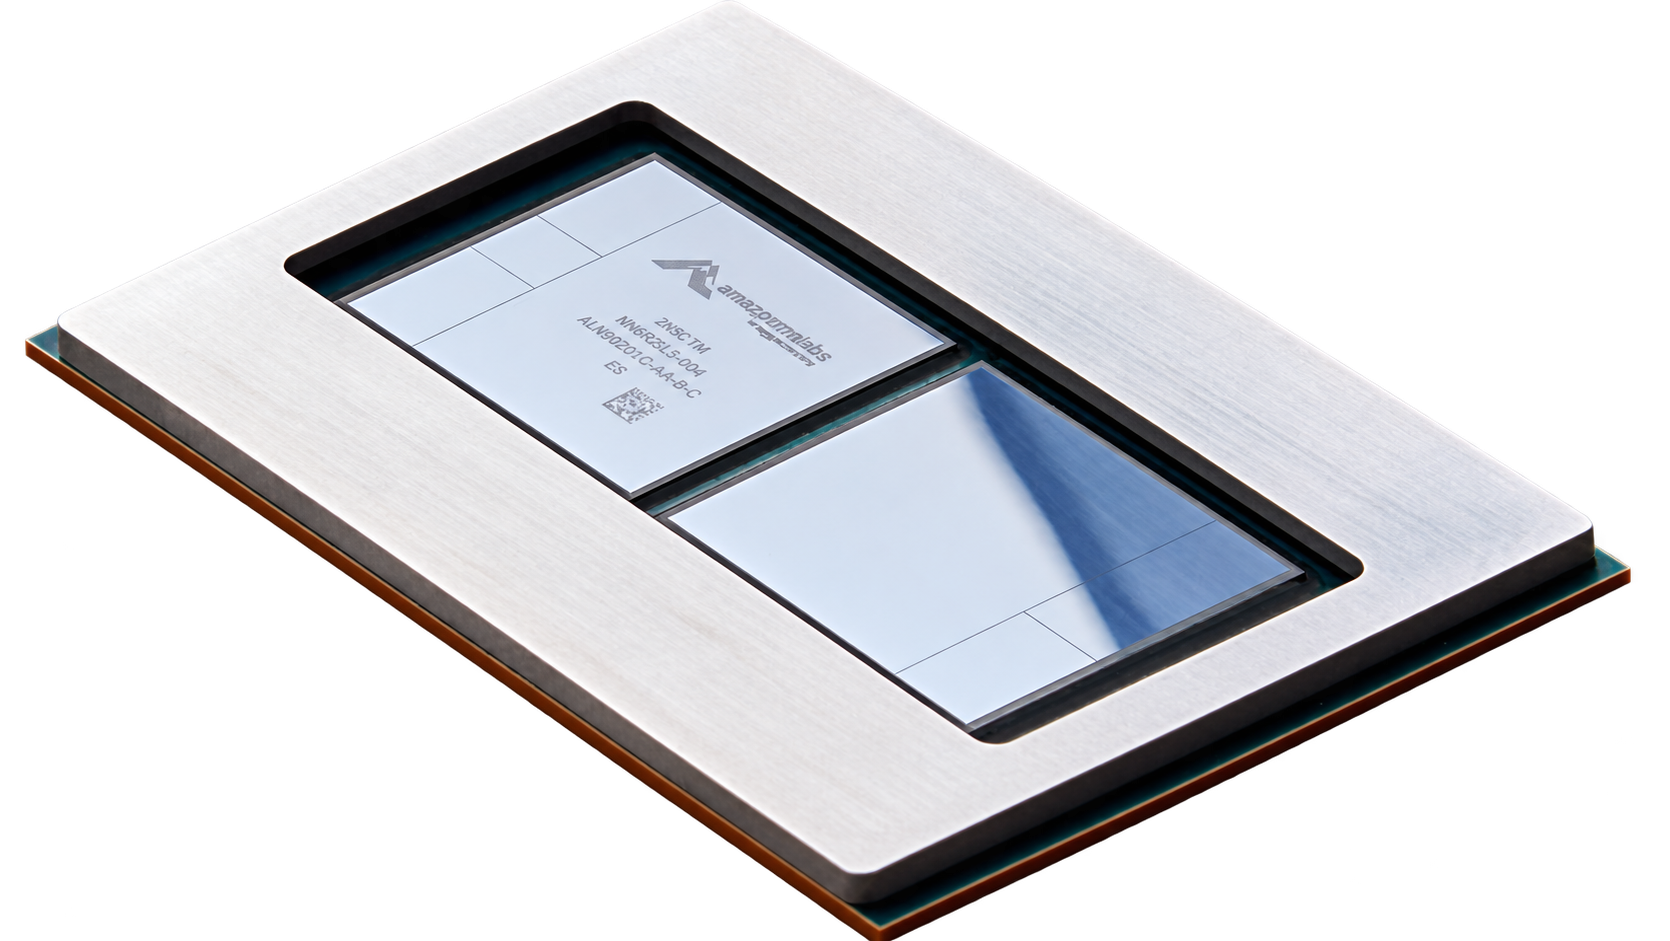
Trainium2
AWS’s second-generation training accelerator, exposed through EC2 Trn2 and UltraServer systems with Neuron software.
Memory
96 GiB HBM
Bandwidth
2.9 TB/s
Instance
16 chips
 Physical hardware
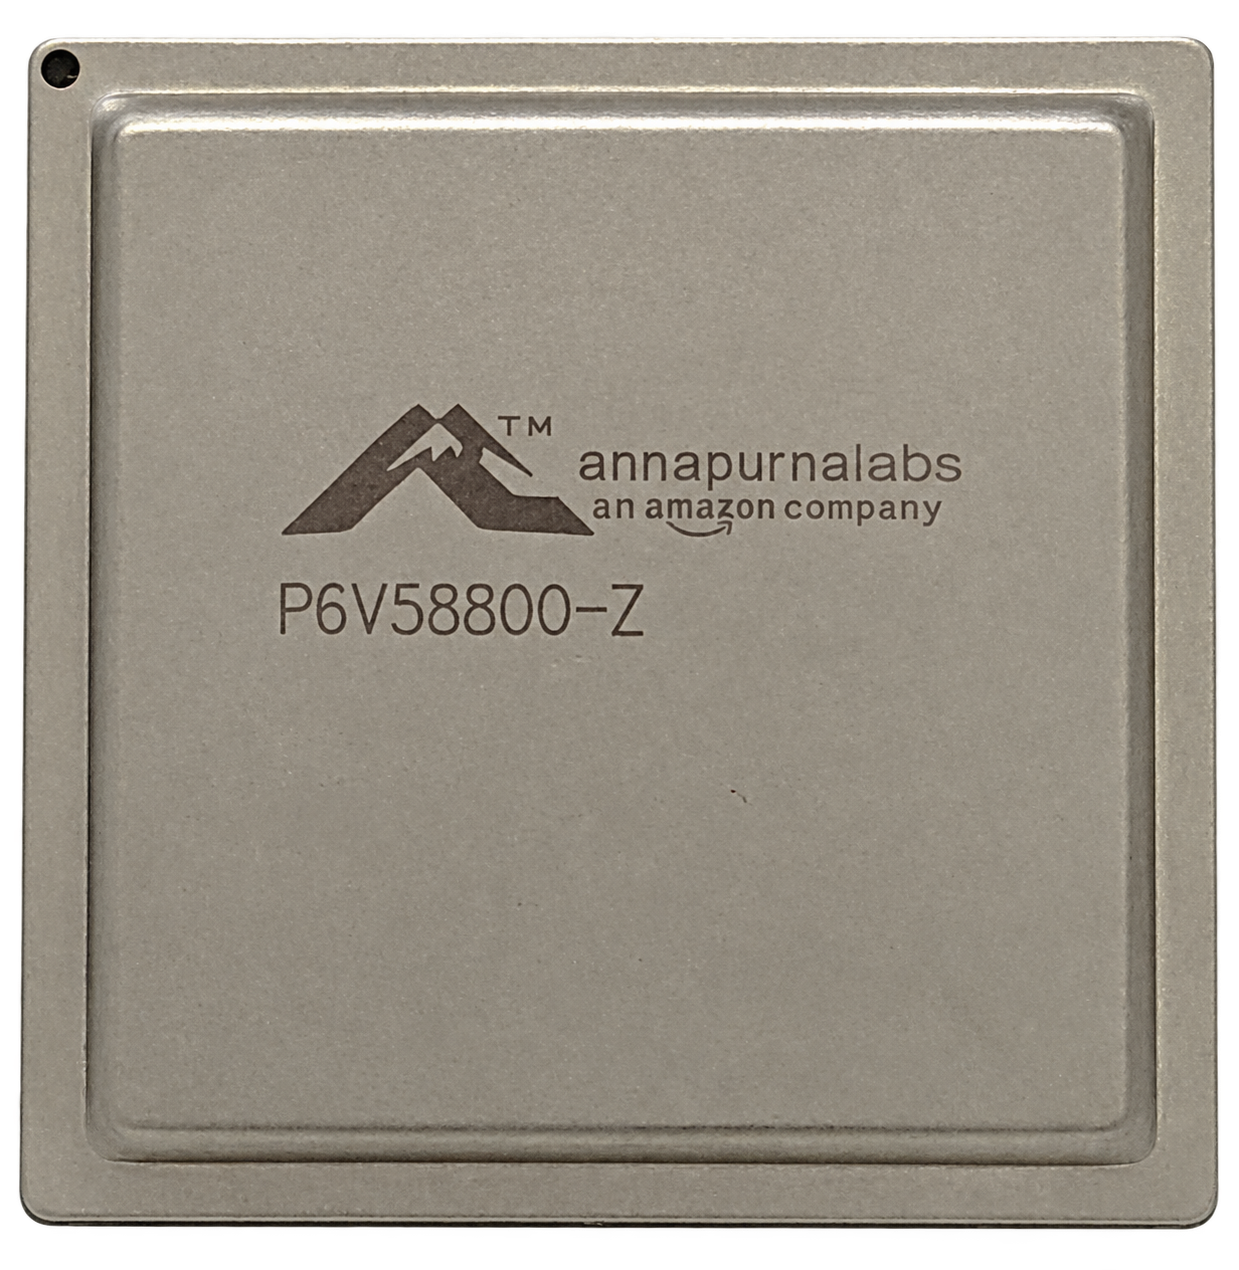
Inferentia2
AWS’s inference-first accelerator for cost-efficient production serving through Inf2 instances and the Neuron SDK.
Instance
Up to 16 chips
Network
Up to 100 Gbps
Software
Neuron SDK
 Physical hardware
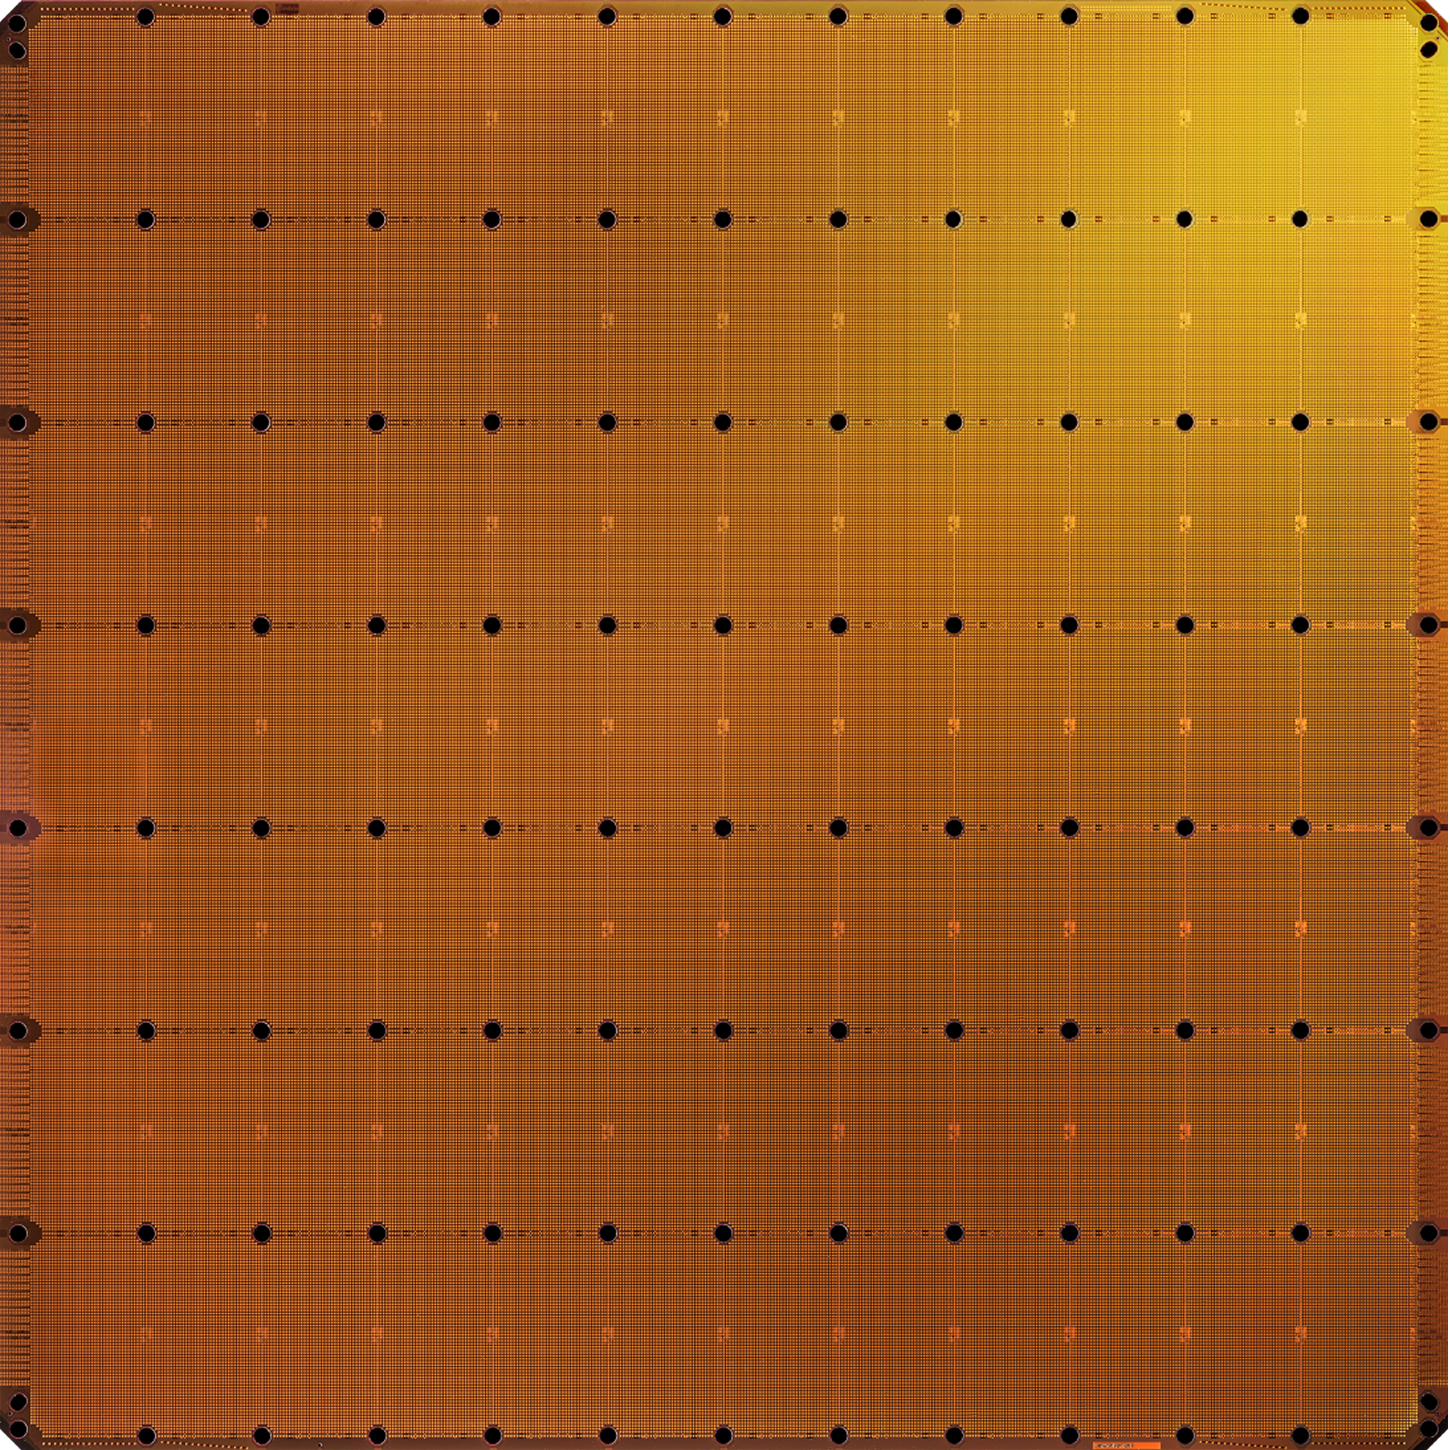
Wafer Scale Engine 3
A 5 nm wafer-scale processor designed to keep model computation on one very large device instead of distributing it across GPU nodes.
AI cores
900,000
On-chip SRAM
44 GB
Peak AI
125 PFLOPS
 Physical hardware
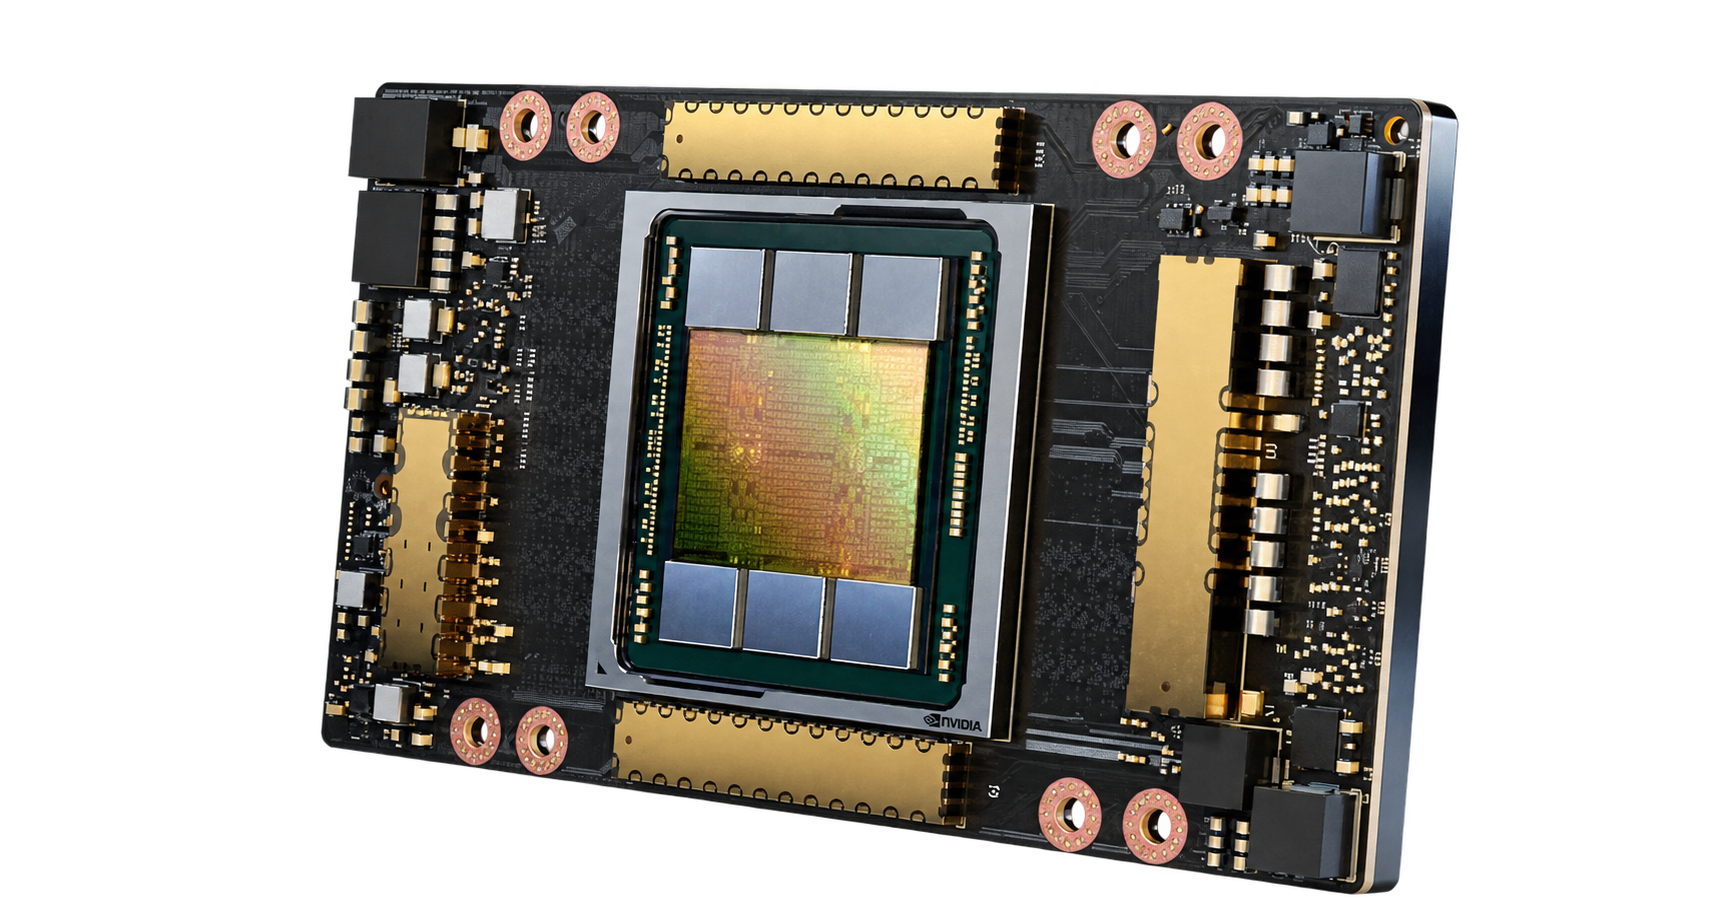
A100 Tensor Core
The established Ampere workhorse for training, inference, analytics, and HPC, still common across cloud fleets.
Memory
80 GB HBM2e
Bandwidth
2.04 TB/s
Power
Up to 400 W
 Physical hardware
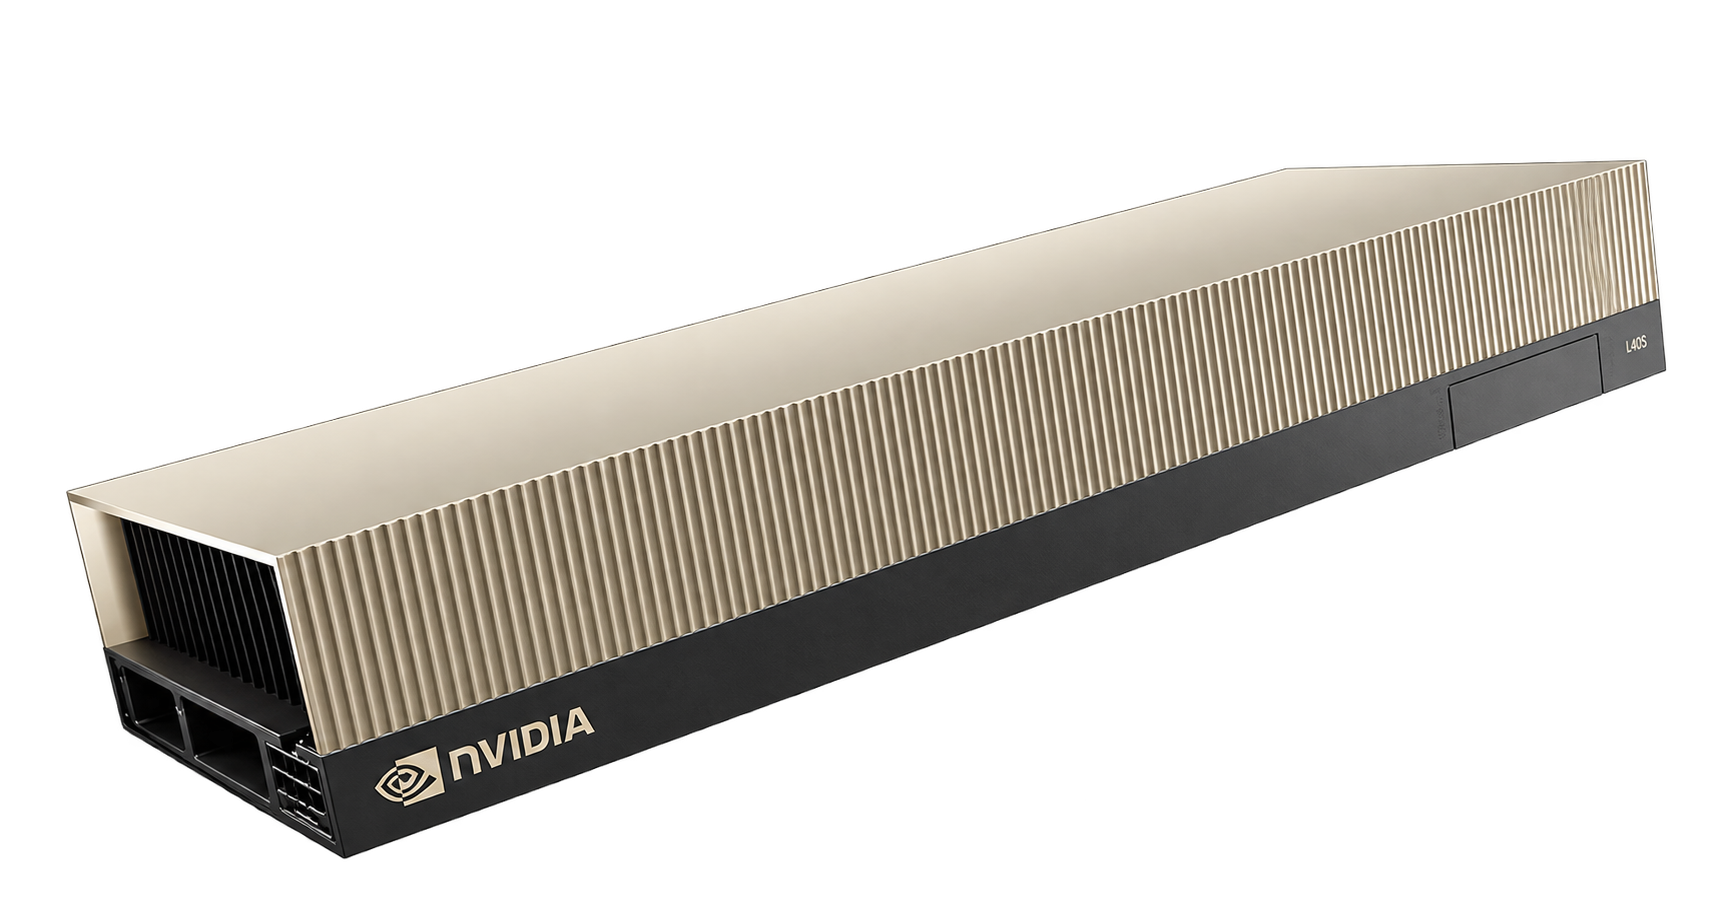
L40S
A PCIe data-center GPU for generative AI inference, rendering, video, and multimodal workloads without NVLink or MIG.
Memory
48 GB GDDR6
Bandwidth
864 GB/s
Power
350 W
 Physical hardware
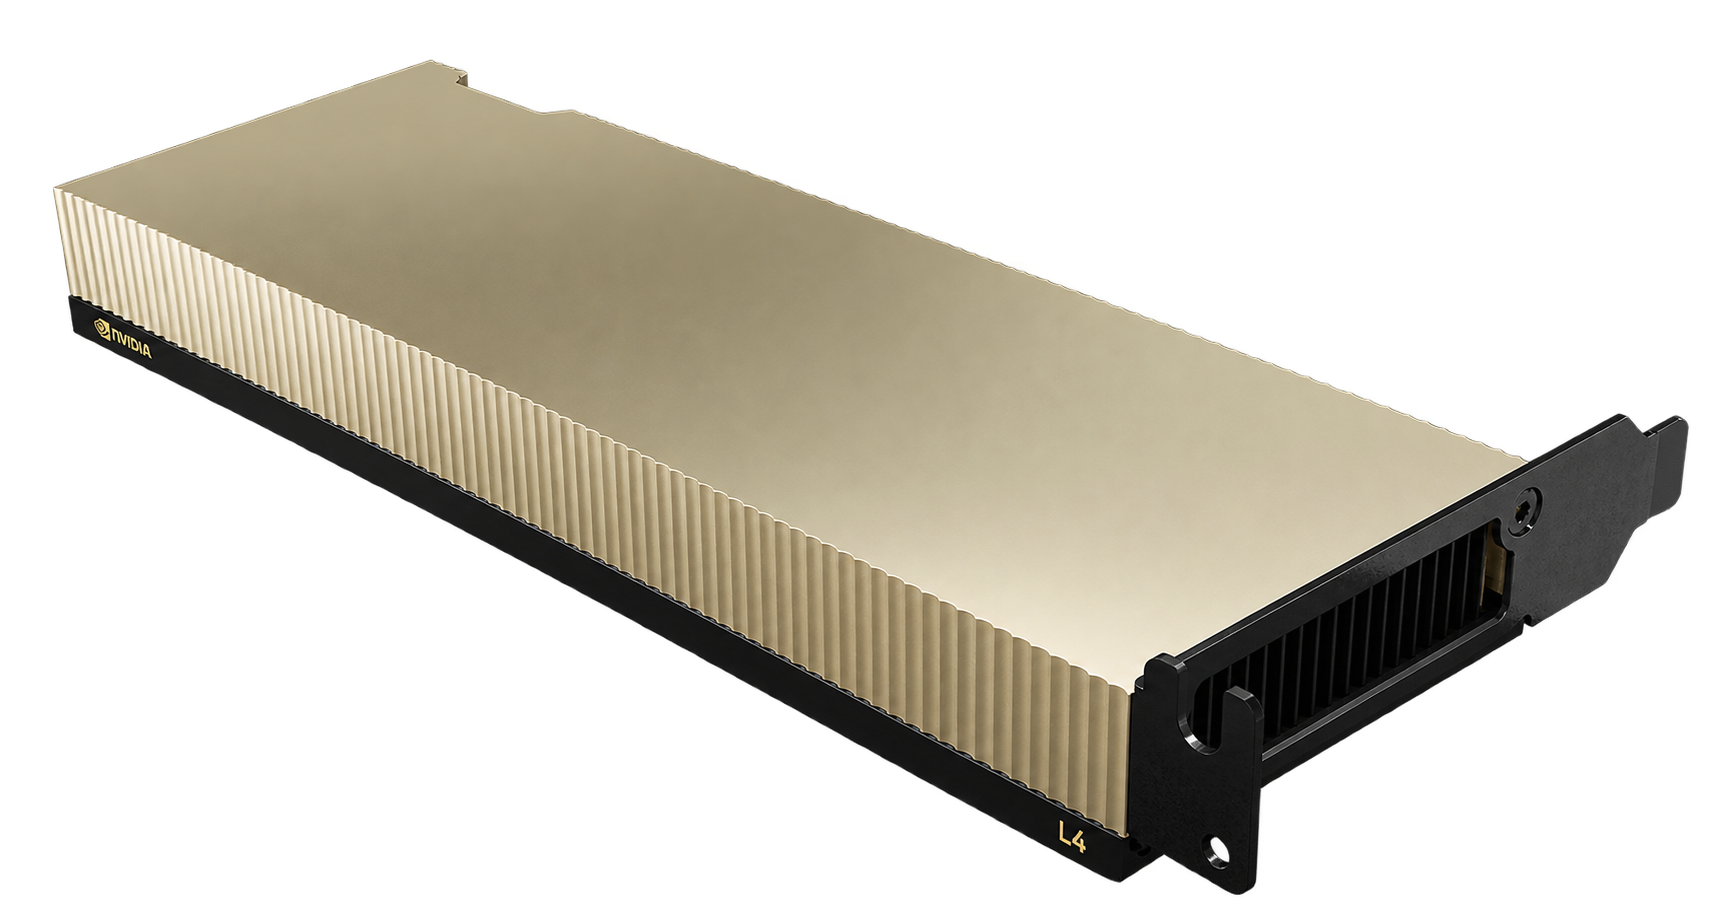
L4 Tensor Core
A compact, low-power PCIe accelerator for video pipelines, edge inference, and cost-sensitive production serving.
Memory
24 GB GDDR6
Bandwidth
300 GB/s
Power
72 W
 Physical hardware
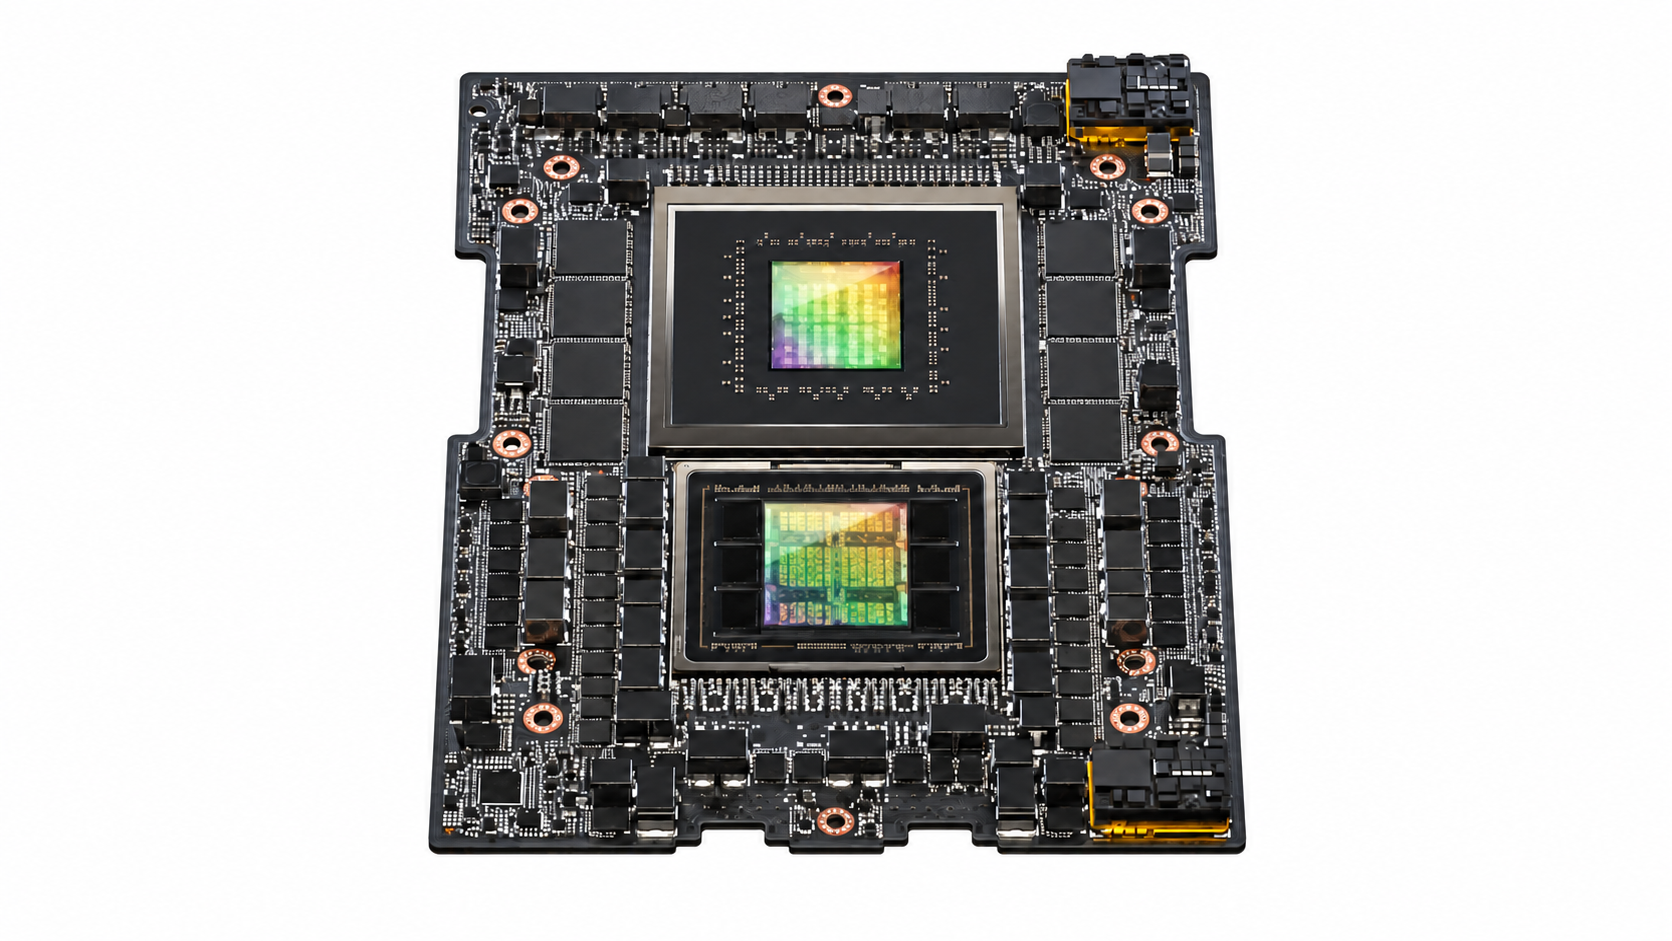
GH200 Grace Hopper
A coherent Grace CPU plus Hopper GPU package that exposes CPU memory as an extension of the GPU memory system.
GPU memory
96 GB HBM3
CPU
Up to 72 Arm cores
CPU–GPU
900 GB/s
 Physical hardware
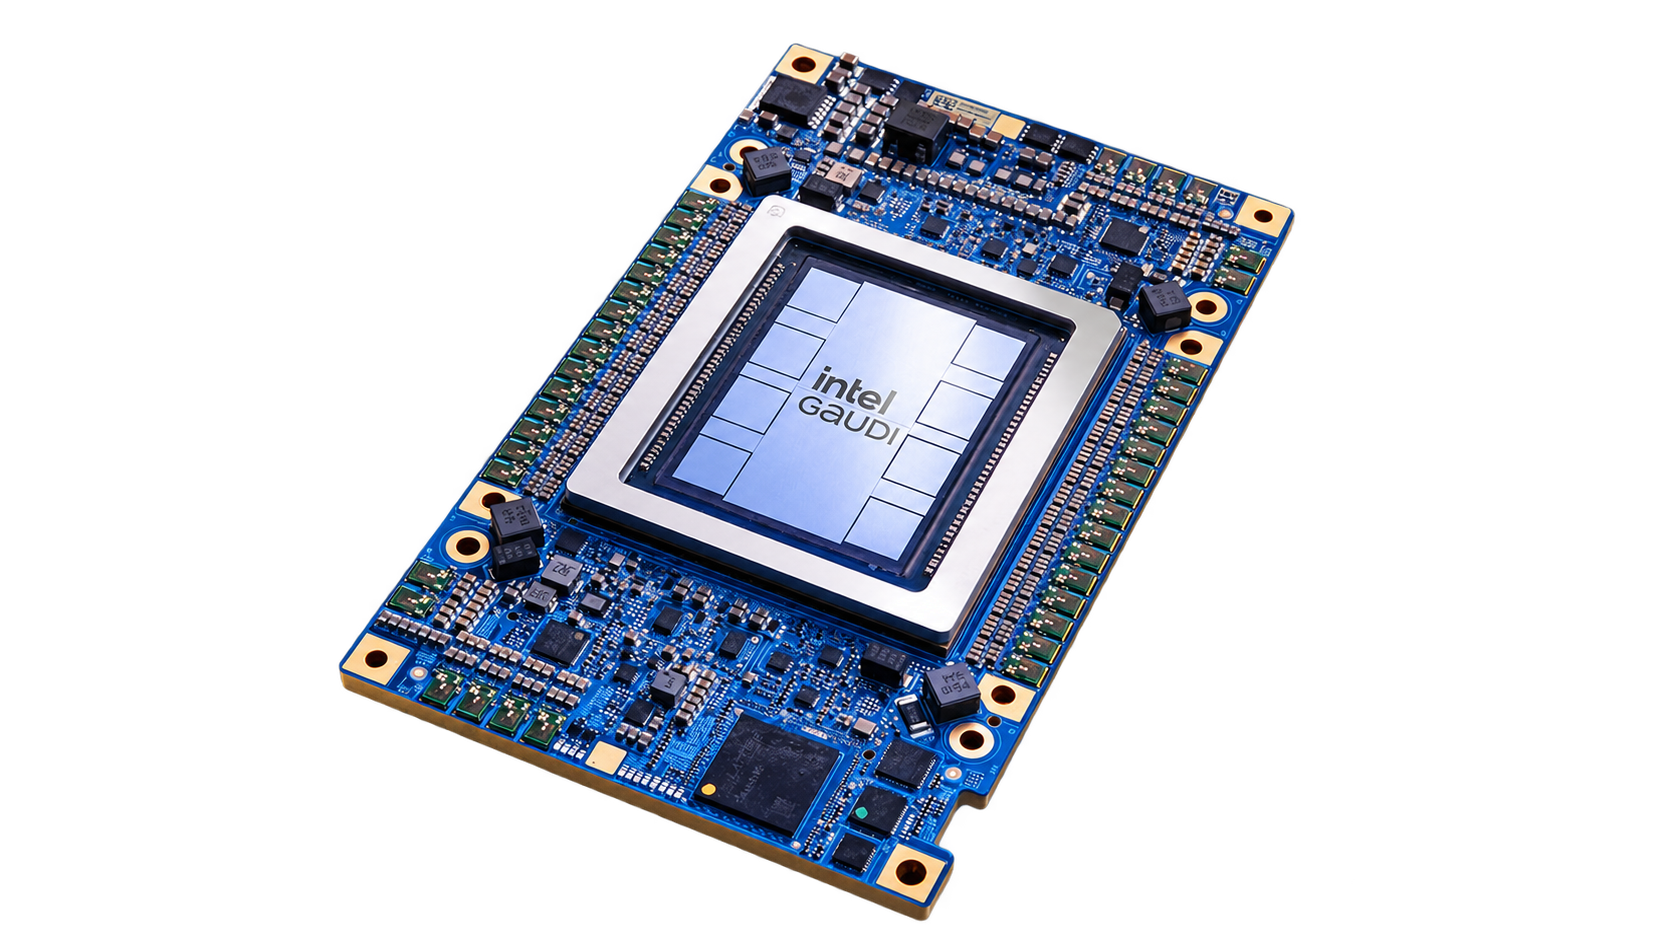
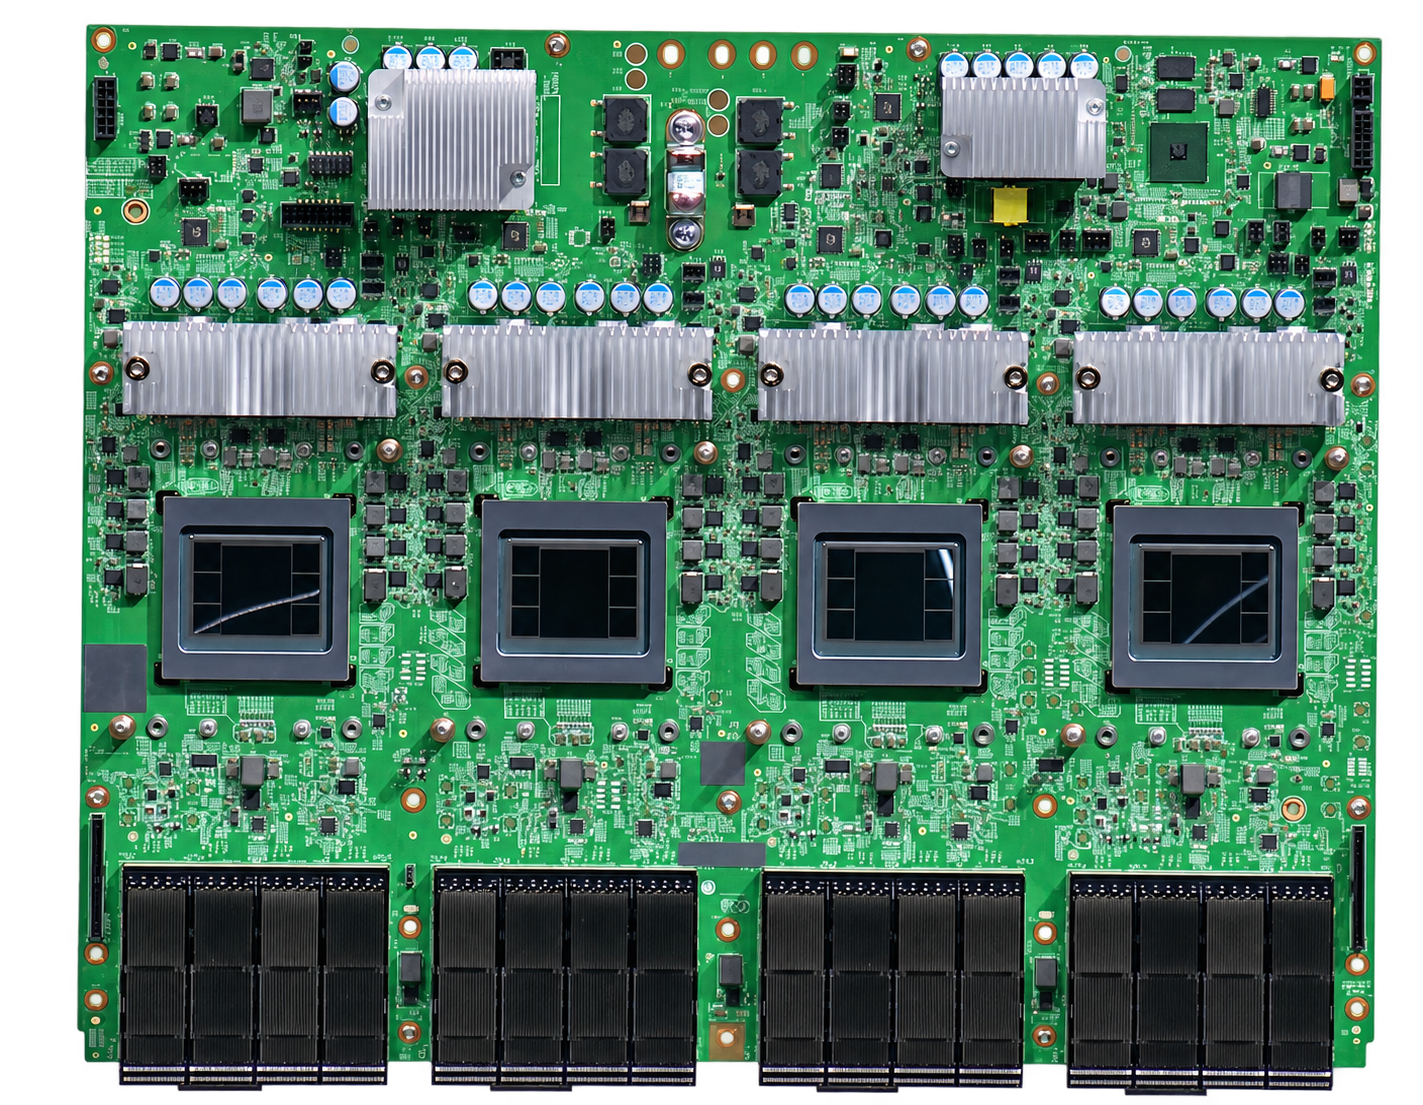
Gaudi 3
An AI accelerator designed around HBM capacity, integrated RoCE networking, and an open software stack for training and inference.
Memory
128 GB HBM2e
Bandwidth
3.67 TB/s
Compute
1,678 TFLOPS
 Physical hardware
Cloud TPU v5p
Google’s large-scale training TPU with 3D-torus slices and enough fabric to schedule jobs across thousands of chips.
Memory
95 GiB HBM
Bandwidth
2,765 GB/s
Pod
8,960 chips
At a glance
Accelerator comparison
| Product | Type | Memory / capacity | Bandwidth / scale | Third signal |
|---|---|---|---|---|
| H100 Tensor Core | GPU | 80 GB HBM3 | 3.35 TB/s | Up to 700 W |
| H200 Tensor Core | GPU | 141 GB HBM3e | 4.8 TB/s | Up to 700 W |
| B200 Tensor Core | GPU | 180 GB HBM3e | Up to 8 TB/s | FP4 / FP6 / FP8 |
| GB200 NVL72 | ASIC | 72 B200 | 30 TB | 130 TB/s |
| Instinct MI300X | GPU | 192 GB HBM3 | 5.3 TB/s | 750 W |
| Instinct MI325X | GPU | 256 GB HBM3e | 6 TB/s | 2 TB HBM3e |
| Instinct MI355X | GPU | 288 GB HBM3e | 8 TB/s | 1,400 W |
| Cloud TPU v6e / Trillium | TPU | 32 GB HBM | 1,638 GB/s | 256 chips |
| Trainium2 | ASIC | 96 GiB HBM | 2.9 TB/s | 16 chips |
| Inferentia2 | ASIC | Up to 16 chips | Up to 100 Gbps | Neuron SDK |
| Wafer Scale Engine 3 | ASIC | 900,000 | 44 GB | 125 PFLOPS |
| A100 Tensor Core | GPU | 80 GB HBM2e | 2.04 TB/s | Up to 400 W |
| L40S | GPU | 48 GB GDDR6 | 864 GB/s | 350 W |
| L4 Tensor Core | GPU | 24 GB GDDR6 | 300 GB/s | 72 W |
| GH200 Grace Hopper | ASIC | 96 GB HBM3 | Up to 72 Arm cores | 900 GB/s |
| Gaudi 3 | ASIC | 128 GB HBM2e | 3.67 TB/s | 1,678 TFLOPS |
| Cloud TPU v5p | TPU | 95 GiB HBM | 2,765 GB/s | 8,960 chips |