Infrastructure atlas NVIDIA/Ampere
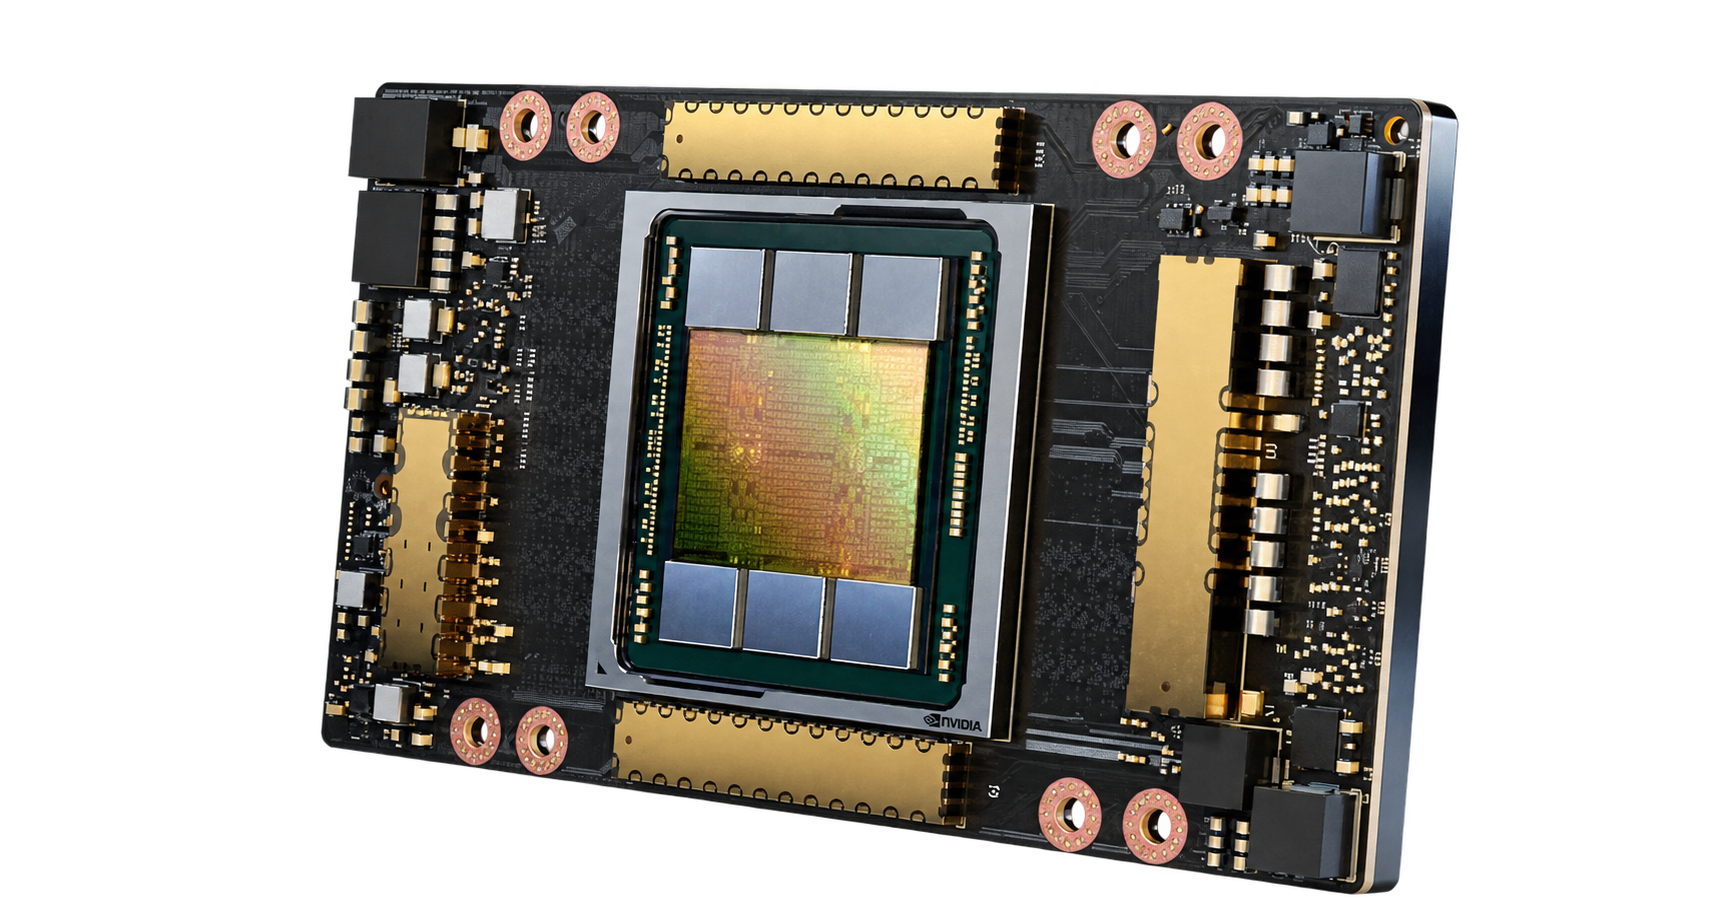
NVIDIA/AmpereA100 Tensor Core
The established Ampere workhorse for training, inference, analytics, and HPC, still common across cloud fleets.
GPUAmperetraininginferenceCUDA
Precision & peak compute
| Precision | Published peak | Basis |
|---|---|---|
| FP16 Tensor | 312 TFLOPS | Dense |
| FP16 Tensor | 624 TFLOPS | Sparse |
| INT8 Tensor | 624 TOPS | Dense |
| INT8 Tensor | 1,248 TOPS | Sparse |
Peak FLOPS and TOPS are theoretical hardware figures. Sparse and dense modes, chip and system totals, and form factors are not interchangeable.
NVIDIA A100 specifications